
Azure OpenAI Development: A Reference Architecture for Secure Enterprise RAG
Most enterprises no longer ask whether generative AI is useful. They ask how to let a language model answer questions about contracts, policies, and case files without exposing that data to the wrong people.
Retrieval-Augmented Generation (RAG) is the pattern most organizations choose. Rather than fine-tuning a model, RAG retrieves relevant passages at query time and passes them to the model as grounding context, so answers come from your data, carry citations, and stay current as documents change.
RAG is easy to prototype and hard to run in production. Pilots often rely on public endpoints, shared API keys, and no document-level permissions. For regulated organizations, Azure OpenAI development is less about the model than the architecture around it. This article lays out that architecture, its data flow, and the controls that move a pilot into production.
What Secure Enterprise RAG Has to Deliver
Five requirements consistently decide whether an enterprise generative AI workload clears security review:
- Identity everywhere: Users, services, and pipelines authenticate through Microsoft Entra ID, with no shared API keys.
- Permission-aware answers: No user receives an answer grounded in a document they cannot open.
- Private data paths: Prompts, embeddings, and documents never cross public endpoints.
- Traceability: Every response maps to its query, sources, model version, and user.
- Operational control: Cost, throughput, safety, and model versions are managed centrally.
Treat these as design inputs, not hardening tasks added after the pilot.
The Reference Architecture: Five Layers
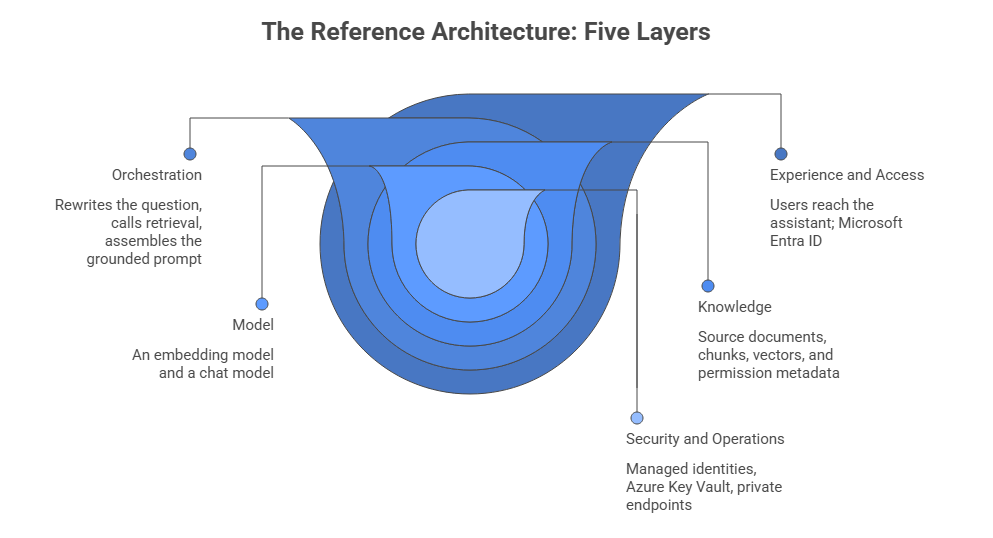
The architecture separates concerns into five layers that can be scaled, secured, and replaced independently, which matters when model versions change every few months.
1. Experience and Access Layer
Users reach the assistant through a web app, Microsoft Teams, or a mobile client on Azure App Service or Azure Container Apps, signing in with Microsoft Entra ID. Azure API Management acts as an AI gateway in front of the models, enforcing token limits, routing traffic, and logging every call.
2. Orchestration Layer
An orchestrator built with Semantic Kernel or LangChain on Azure Container Apps rewrites the question, calls retrieval, assembles the grounded prompt, and formats citations. Foundry Agent Service suits multi-step, tool-using assistants.
3. Knowledge Layer
Azure Blob Storage or ADLS Gen2 holds source documents. Azure AI Document Intelligence extracts text and tables from PDFs and scans. Azure AI Search stores chunks, vectors, and permission metadata, and serves hybrid keyword and vector queries with semantic ranking.
4. Model Layer
Azure OpenAI models, now delivered through Microsoft Foundry, run as two deployments: an embedding model and a chat model. Azure AI Content Safety, including Prompt Shields, screens prompts and responses for harmful content and injection attempts.
5. Security and Operations Plane
Managed identities, Azure Key Vault, private endpoints in an Azure Virtual Network, Azure Monitor, Microsoft Defender for Cloud, and Microsoft Purview span every layer.
End-to-End Data Flow
Two pipelines run side by side, and both must carry identity and permissions end to end.
Ingestion Path
- Documents land in Blob Storage or ADLS Gen2 from SharePoint, file shares, or business systems.
- An Azure AI Search indexer or Azure Functions pipeline picks up new and changed files.
- Document Intelligence parses the content, which is chunked and embedded by Azure OpenAI.
- Chunks, vectors, metadata, and access control entries (Entra IDs or RBAC scopes) are written to the index.
Query Path
- The user signs in with Entra ID, and the request passes through API Management to the orchestrator.
- Azure AI Search runs a hybrid query and trims results to documents the user may access.
- The top chunks form a grounded prompt, and Azure OpenAI generates the answer.
- Content Safety screens the response, which returns with citations, and the exchange is logged for audit.
Security and Governance Controls
No single control is sufficient. Together, these close the gaps that typically stall production approval.
Identity and Role-Based Access Control
Use managed identities for every service-to-service call and disable key-based authentication where supported. Assign narrow Azure RBAC roles, such as Cognitive Services OpenAI User and Search Index Data Reader, and give administrators just-in-time access through Entra Privileged Identity Management.
Document-Level Security
This is the control most pilots skip. Azure AI Search supports native document-level access control: it stores permission metadata with each chunk, validates the caller’s Entra token at query time, and returns only authorized documents. It can also honor SharePoint permissions and Purview sensitivity labels, while other sources can use security filters. Some features remain in preview, so confirm regional availability.
Network Isolation
Place Azure OpenAI, AI Search, Storage, and Key Vault behind private endpoints with public access disabled, and control egress through Azure Firewall in a hub-and-spoke network.
Secrets, Encryption, and Data Handling
Keep remaining secrets in Azure Key Vault and use customer-managed keys where policy requires. Microsoft states that Azure OpenAI prompts and completions are not used to train OpenAI’s foundation models.
Content Safety, Monitoring, and Audit
Apply Prompt Shields and content filters to inputs and outputs, centralize logs in Log Analytics, and monitor posture with Defender for Cloud, ideally within a responsible AI governance program and an ongoing cloud security posture management practice.
Implementation and Scalability Considerations
Most RAG quality problems are retrieval problems, not model problems.
Retrieval Quality
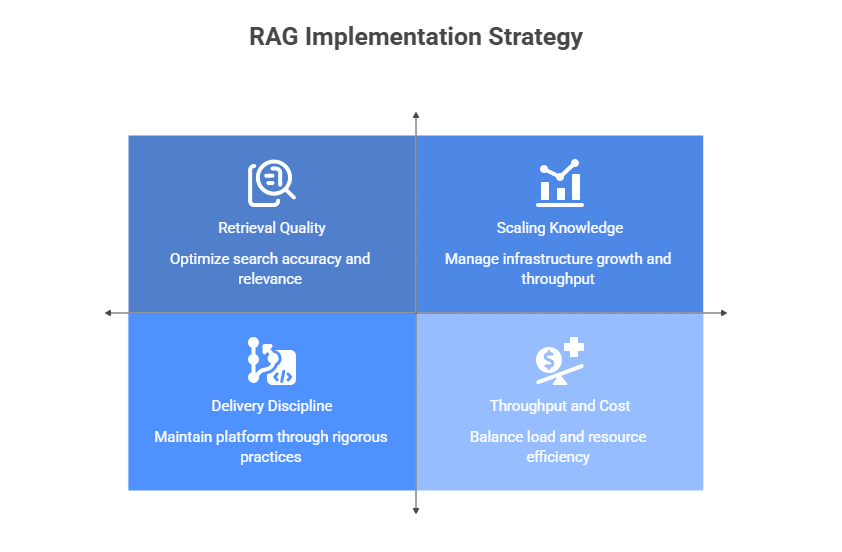
Chunk on document structure rather than fixed character counts, and keep titles and metadata with each chunk. Default to hybrid search with semantic ranking, since pure vector search misses exact terms like policy numbers. Score groundedness and relevance against real user questions on every change using Microsoft Foundry evaluations.
Throughput and Cost
Standard and global deployments suit early or variable workloads, while provisioned throughput pays off once usage is predictable. API Management balances load across regions, caches repeated questions, and attributes token usage to each business unit.
Scaling the Knowledge Layer
Azure AI Search scales through replicas for query volume and partitions for index size. Incremental indexing avoids full rebuilds as content grows.
Delivery Discipline
Define resources in Bicep or Terraform, pin model versions, and promote changes through dev, test, and production. Mature AI infrastructure and MLOps and cloud development practices keep the platform maintainable.
Common Challenges and How to Address Them
| Challenge | How to address it |
|---|---|
| Permission leakage | Store Entra IDs or RBAC scopes per chunk and enforce trimming at query time |
| Confident but wrong answers | Structure-aware chunking, hybrid search, groundedness evaluation |
| Stale knowledge | Change-driven incremental indexing |
| Throttling at peak load | API Management load balancing and provisioned throughput |
| Unpredictable cost | Per-team token metering, semantic caching, right-sized models |
| Prompt injection via documents | Prompt Shields, strict system prompts, human approval for actions |
Where Secure Enterprise RAG Delivers Value
- Employee knowledge assistants: HR, IT, and policy answers from SharePoint and document management systems, scoped to each employee’s role, as in our generative AI intranet portal.
- Field and engineering support: Technicians in oil and gas or manufacturing query manuals and safety procedures from mobile devices.
- Healthcare operations: Staff search protocols and payer policies inside a HIPAA-aligned Azure environment.
- Government services: Agencies ground resident and staff assistants in ordinances and program rules, as with an AI chatbot for government agencies.
- Legal and contract review: Teams locate clauses and obligations across large repositories with verifiable citations.
Recommendations for Enterprise Leaders
- Start with one permission-sensitive use case: Proving document-level security on a real corpus builds more confidence than a broad, unsecured pilot.
- Decide identity and networking on day one: Retrofitting private endpoints and managed identities costs more than building them in.
- Treat retrieval as the product: Improve parsing, chunking, and evaluation before reaching for a larger model, a core principle of sound AI and machine learning development.
- Put a gateway in front of every model: API Management delivers cost control, failover, and audit without code changes.
- Plan beyond Q&A: Today’s RAG assistant often becomes tomorrow’s copilot or agent. Our guide to chatbots, copilots, and AI agents explains how those paths differ.
Build Secure Enterprise RAG with App Maisters
Azure OpenAI development succeeds when security, retrieval quality, and operations are designed together. App Maisters, a Microsoft Azure partner, combines generative AI development, cloud consulting, and enterprise application development to move RAG from proof of concept to governed production, backed by ISO 9001 and ISO 27001 certified delivery for businesses of all sizes.
Evaluating an Azure RAG architecture or hardening an existing pilot? Talk to our Azure AI team about an architecture and security review.
FAQs
What is Azure OpenAI development, and how is it different from using ChatGPT?
Azure OpenAI development means building applications on OpenAI models hosted inside Microsoft Azure, now delivered through Microsoft Foundry. Unlike consumer ChatGPT, the models run within your Azure tenant with Entra ID authentication, private networking, and enterprise compliance controls. App Maisters uses Azure OpenAI to build custom copilots, chatbots, and RAG applications connected to a company’s own data and systems.
Is Azure OpenAI secure, and does it use my data to train models?
Microsoft states that Azure OpenAI does not use customer prompts, completions, or embeddings to train or improve OpenAI’s foundation models, and that this data is not shared with OpenAI. Security still depends on configuration. App Maisters hardens each deployment with managed identities, private endpoints, Key Vault, and content filtering, backed by ISO 27001 certified delivery practices.
How does RAG work with Azure AI Search?
Azure AI Search indexes your documents as chunks with vector embeddings and metadata. When a user asks a question, the application runs a hybrid keyword and vector search, retrieves the most relevant passages, and passes them to an Azure OpenAI chat model as grounding context. App Maisters designs this Azure RAG architecture so every answer includes citations users can verify.
Is RAG better than fine-tuning for enterprise generative AI?
For most knowledge-based use cases, yes. RAG keeps answers current as documents change, supports citations, and enforces access control at query time, while fine-tuning is better suited to teaching a model a specific style, format, or narrow task. App Maisters typically recommends starting with RAG and adding fine-tuning only when evaluation shows a clear gap.
Can an Azure RAG chatbot respect SharePoint and document-level permissions?
Yes. Azure AI Search supports document-level access control that validates the user’s Microsoft Entra token and returns only content that user is authorized to see, including SharePoint permissions and Purview sensitivity labels. Some of these features are in preview. App Maisters builds permission-aware retrieval into secure enterprise RAG systems from the first release, not as a later fix.
Is Azure OpenAI HIPAA compliant for healthcare RAG applications?
Azure OpenAI can be used in HIPAA-regulated workloads under Microsoft’s Business Associate Agreement, but compliance depends on how the full solution is designed, configured, and operated. App Maisters builds healthcare RAG applications with private networking, audit logging, encryption, and least-privilege access, drawing on its experience delivering HIPAA-compliant healthcare software.
How much does it cost to build a secure RAG solution on Azure?
Based on 2026 market estimates, a proof of concept typically costs $20,000 to $50,000, a departmental production system $50,000 to $120,000, and an enterprise-wide secure RAG platform $120,000 to $300,000 or more. Ongoing Azure costs range from about $1,000 to $3,000 per month for pilots to over $10,000 per month at enterprise scale. App Maisters provides a scoped architecture review and estimate so businesses of all sizes can budget with confidence.